fcp_2910_collision · branch v5.31 · GTX 1650 (4 GB), 12 CPU threads · 6144 atoms, 128 layers · generated 2026-10-29 11:47
scripts/fcpq.py). A point is inside when the signed sum over the
parts spanning its height of "inside the part's ring at that height" is positive (hole parts count −1). The ring at
height s comes from one of two modes:
table evaluates the rings once at the layer centres (128 vertices each, from the stored polynomial: about 5 ms per
object, no mesh, no grid). A query blends the two neighbouring rings vertex by vertex and runs an even-odd crossing test.
Edges are pre-binned in y (32 bins per layer interval), so a query reads only the few edges that its ray can cross.
poly evaluates the stored Chebyshev × Fourier polynomial at the exact height for every query (2K coefficients,
then the NT ring vertices), followed by the same crossing test.
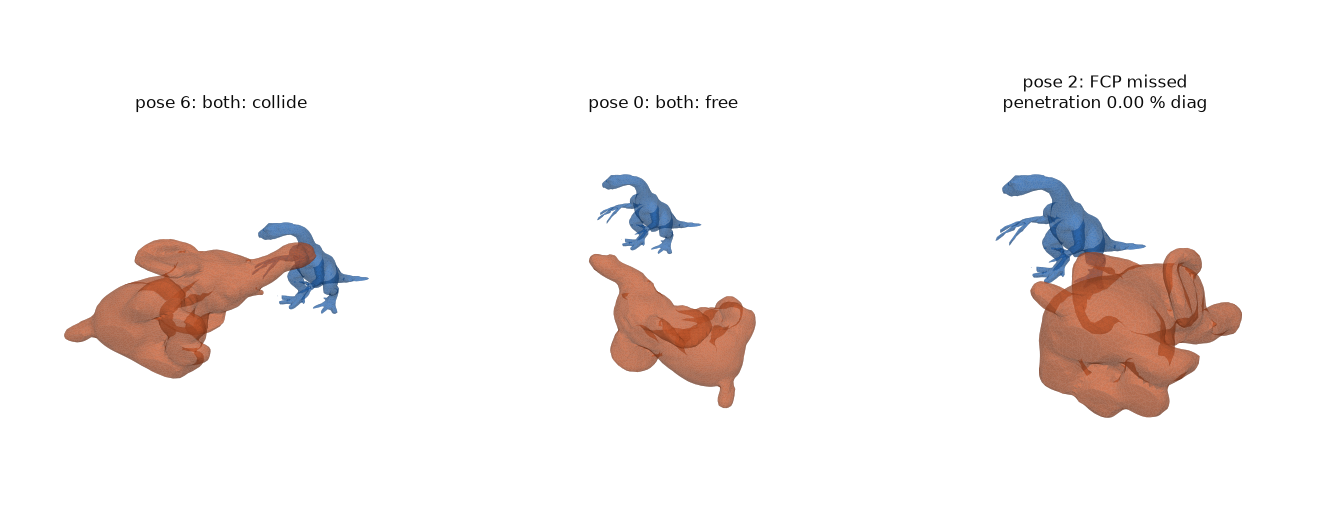
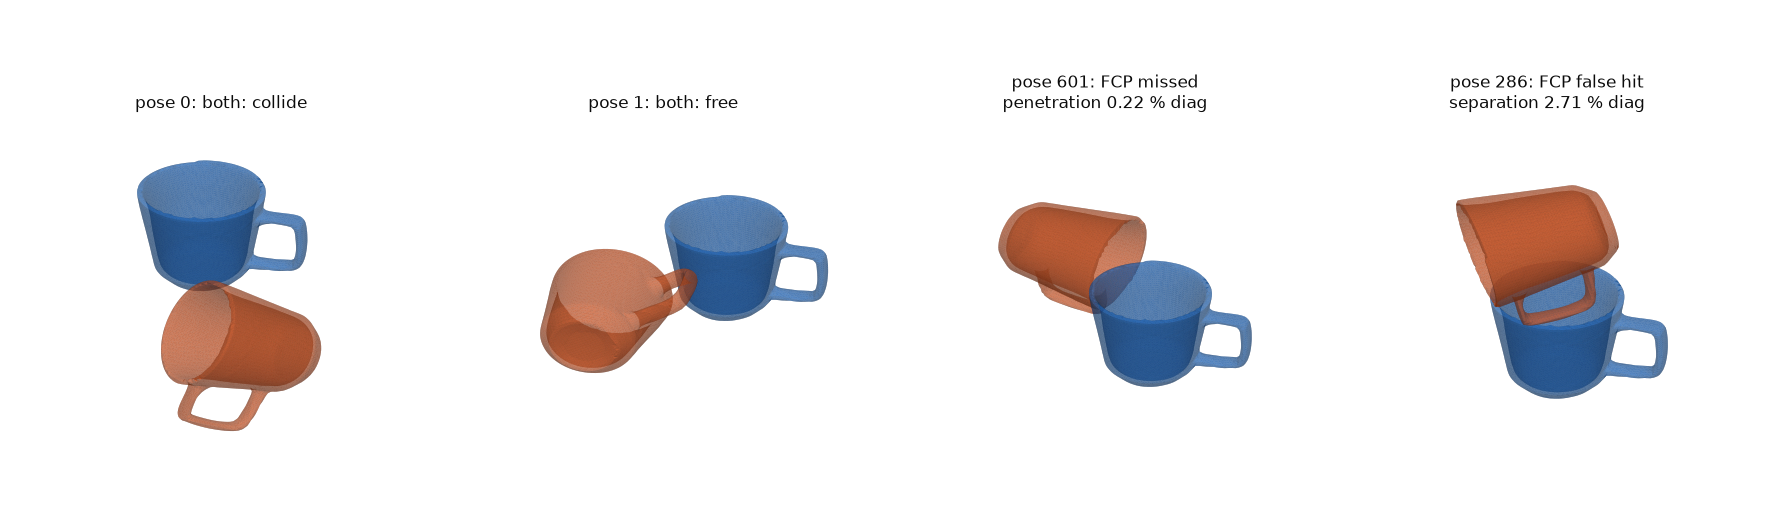
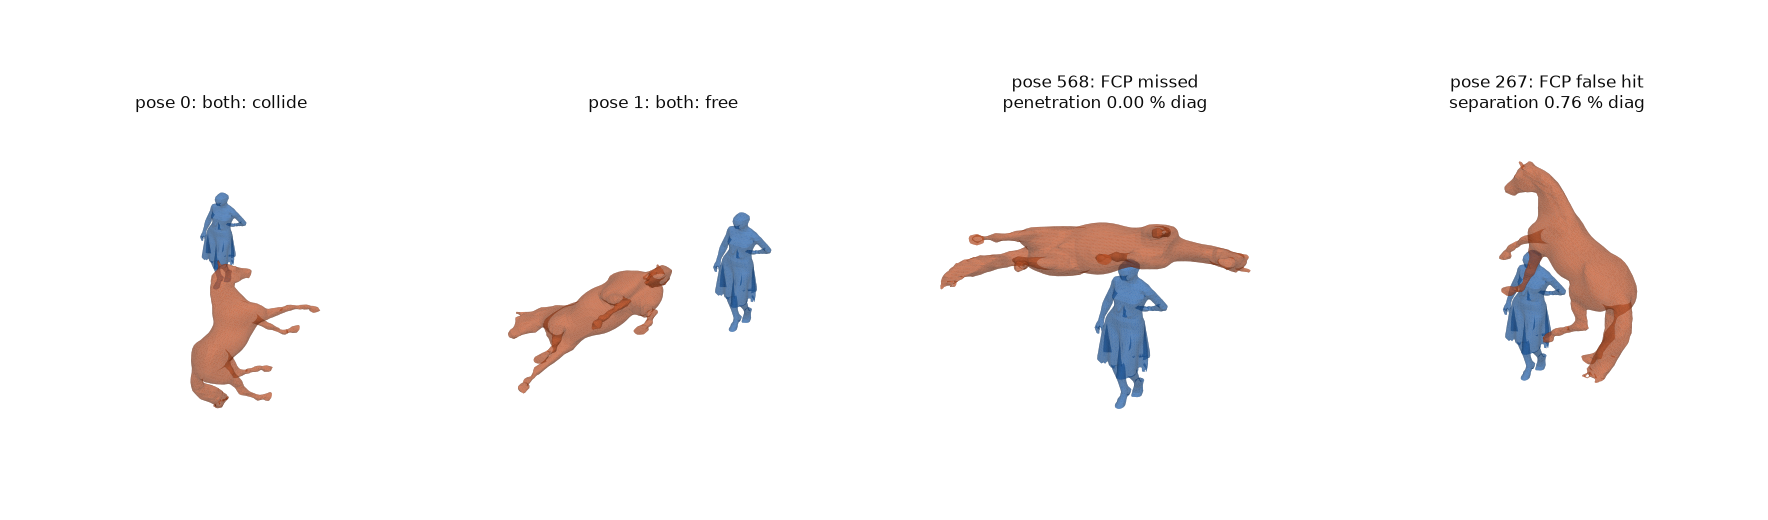
Collision: the table ring vertices of each object, optionally strided in layers × vertices, are mapped into the other's
canonical frame and tested. A pose collides when any vertex is inside. All poses run in one CUDA launch (or a numba
prange). CPU and GPU give the same answers.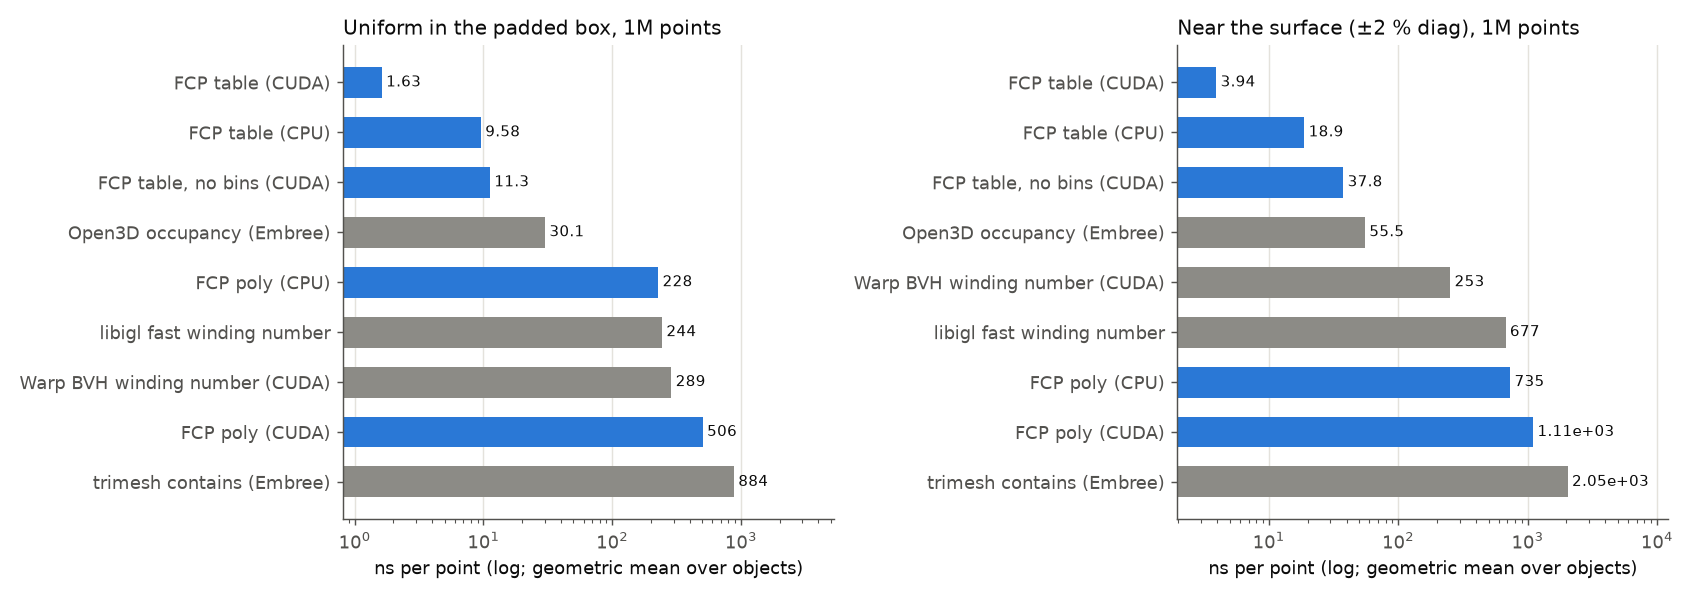
| method | device | mug ns/pt | bowl ns/pt | dino ns/pt | elephant ns/pt | shoe ns/pt | horse ns/pt | dress ns/pt | geo-mean ns/pt | × vs Open3D | build ms (mean) | wrong vs mesh % | wrong vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
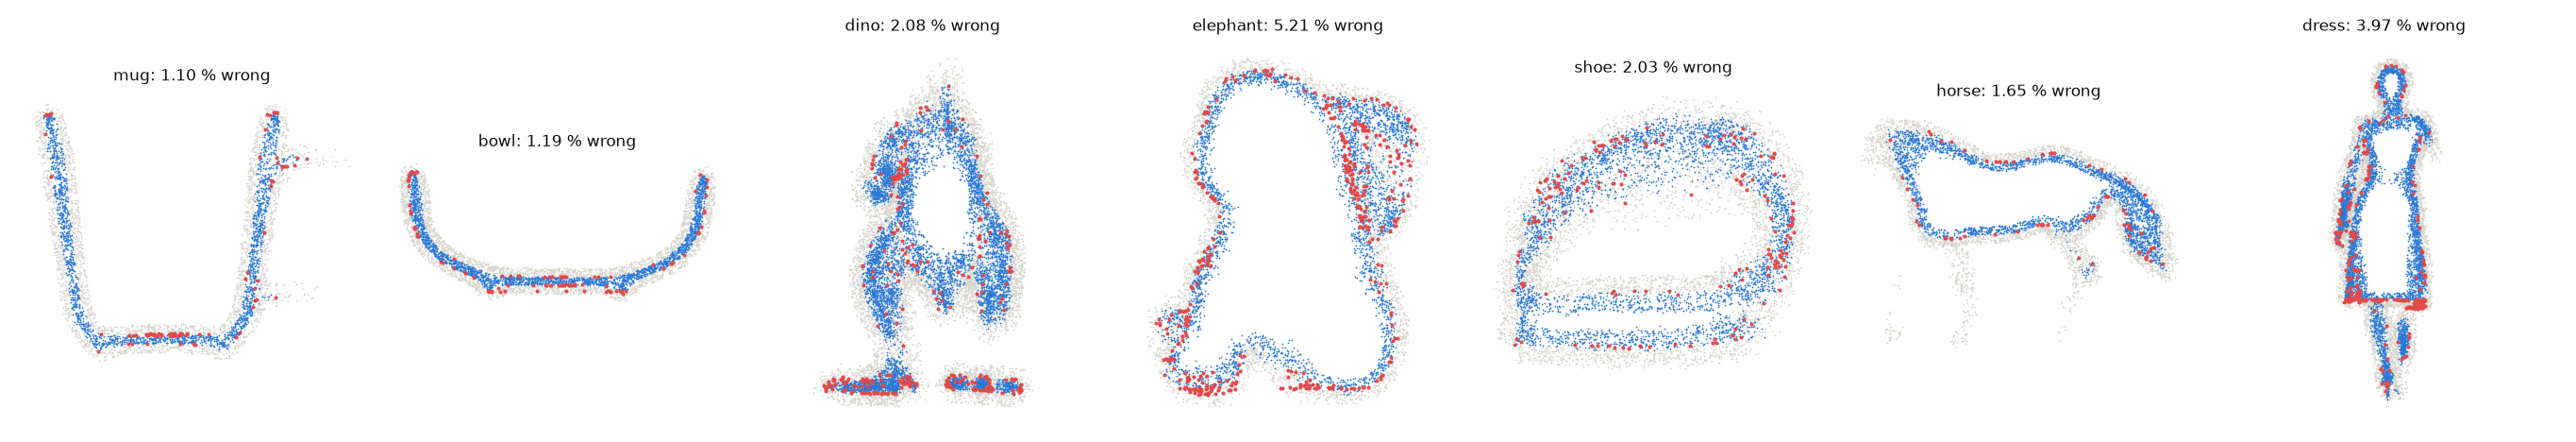
| FCP table (CUDA) | gpu | 3.58 | 3.83 | 4.06 | 4.05 | 3.94 | 3.72 | 4.43 | 3.94 | 14.1 | 4.99 | 2.42 | |
| FCP table (CPU) | cpu | 19 | 17.2 | 22 | 19.1 | 19.3 | 16.9 | 19 | 18.9 | 2.9 | 4.99 | 2.42 | |
| FCP table, no bins (CUDA) | gpu | 51.1 | 55 | 29.9 | 32.3 | 41 | 30.5 | 32.1 | 37.8 | 1.5 | 4.99 | 2.42 | |
| Open3D occupancy (Embree) | cpu | 55.1 | 66 | 47.8 | 60.4 | 55.1 | 40.5 | 69.3 | 55.5 | 1.0 | 0.644 | 0.00 | |
| Warp BVH winding number (CUDA) | gpu | 117 | 163 | 228 | 431 | 270 | 159 | 829 | 253 | 0.2 | 3.9 | 0.00 | |
| libigl fast winding number | cpu | 862 | 713 | 630 | 620 | 855 | 553 | 577 | 677 | 0.1 | 29.6 | 0.00 | |
| FCP poly (CPU) | cpu | 1.02e+03 | 1.05e+03 | 638 | 604 | 749 | 616 | 609 | 735 | 0.1 | 4.99 | 3.01 | |
| FCP poly (CUDA) | gpu | 831 | 565 | 1.36e+03 | 1.41e+03 | 1.43e+03 | 1.26e+03 | 1.25e+03 | 1.11e+03 | 0.1 | 4.99 | 3.01 |
| method | device | mug ns/pt | bowl ns/pt | dino ns/pt | elephant ns/pt | shoe ns/pt | horse ns/pt | dress ns/pt | geo-mean ns/pt | × vs Open3D | build ms (mean) | wrong vs mesh % | wrong vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FCP table (CUDA) | gpu | 2.19 | 1.99 | 1.02 | 1.89 | 2.05 | 1.14 | 1.54 | 1.63 | 18.5 | 4.99 | 0.28 | |
| FCP table (CPU) | cpu | 10.3 | 9.72 | 9.26 | 10.5 | 11.7 | 7.92 | 8.25 | 9.58 | 3.1 | 4.99 | 0.28 | |
| FCP table, no bins (CUDA) | gpu | 28.7 | 29.6 | 2.91 | 10.2 | 18.1 | 6.62 | 7.56 | 11.3 | 2.7 | 4.99 | 0.28 | |
| Open3D occupancy (Embree) | cpu | 32.3 | 41.4 | 20.7 | 31.7 | 32.6 | 21.9 | 36.1 | 30.1 | 1.0 | 0.644 | 0.00 | |
| FCP poly (CPU) | cpu | 473 | 571 | 87.9 | 182 | 314 | 176 | 135 | 228 | 0.1 | 4.99 | 0.36 | |
| libigl fast winding number | cpu | 371 | 271 | 120 | 210 | 413 | 186 | 269 | 244 | 0.1 | 29.6 | 0.00 | |
| Warp BVH winding number (CUDA) | gpu | 122 | 250 | 225 | 557 | 249 | 167 | 1.05e+03 | 289 | 0.1 | 3.9 | 0.00 | |
| FCP poly (CUDA) | gpu | 584 | 372 | 296 | 631 | 851 | 513 | 477 | 506 | 0.1 | 4.99 | 0.36 |
| method | device | mug ns/pt | bowl ns/pt | dino ns/pt | elephant ns/pt | shoe ns/pt | horse ns/pt | dress ns/pt | geo-mean ns/pt | × vs Open3D | build ms (mean) | wrong vs mesh % | wrong vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FCP table (CUDA) | gpu | 6.88 | 7.16 | 7.73 | 8.67 | 7.61 | 6.75 | 9.11 | 7.66 | 10.9 | 4.99 | 2.53 | 1.11 |
| FCP table (CPU) | cpu | 20.3 | 18 | 20.8 | 20.5 | 20.5 | 19.7 | 220 | 28.1 | 3.0 | 4.99 | 2.53 | 1.11 |
| FCP table, no bins (CUDA) | gpu | 58.3 | 60.4 | 36.7 | 43.3 | 48.5 | 35.9 | 38.8 | 45.1 | 1.8 | 4.99 | 2.53 | 1.11 |
| Open3D occupancy (Embree) | cpu | 88.8 | 87.5 | 75.2 | 94.5 | 83.2 | 62 | 96.6 | 83.2 | 1.0 | 0.644 | 0.00 | 2.03 |
| Warp BVH winding number (CUDA) | gpu | 125 | 153 | 207 | 400 | 240 | 169 | 948 | 250 | 0.3 | 3.9 | 0.00 | 2.03 |
| FCP poly (CPU) | cpu | 1.04e+03 | 1.06e+03 | 638 | 613 | 744 | 881 | 613 | 778 | 0.1 | 4.99 | 3.10 | 2.01 |
| FCP poly (CUDA) | gpu | 1.1e+03 | 780 | 1.51e+03 | 1.65e+03 | 1.62e+03 | 1.63e+03 | 1.5e+03 | 1.36e+03 | 0.1 | 4.99 | 3.10 | 2.01 |
| trimesh contains (Embree) | cpu | 1.95e+03 | 1.87e+03 | 1.64e+03 | 2.46e+03 | 2.21e+03 | 1.7e+03 | 2.71e+03 | 2.05e+03 | 0.0 | 70.5 | 0.00 | 2.03 |
| libigl fast winding number | cpu | 1.4e+03 | 1.52e+03 | 1.87e+03 | 2.47e+03 | 2.35e+03 | 1.78e+03 | 1.48e+04 | 2.5e+03 | 0.0 | 29.6 | 0.00 | 2.03 |
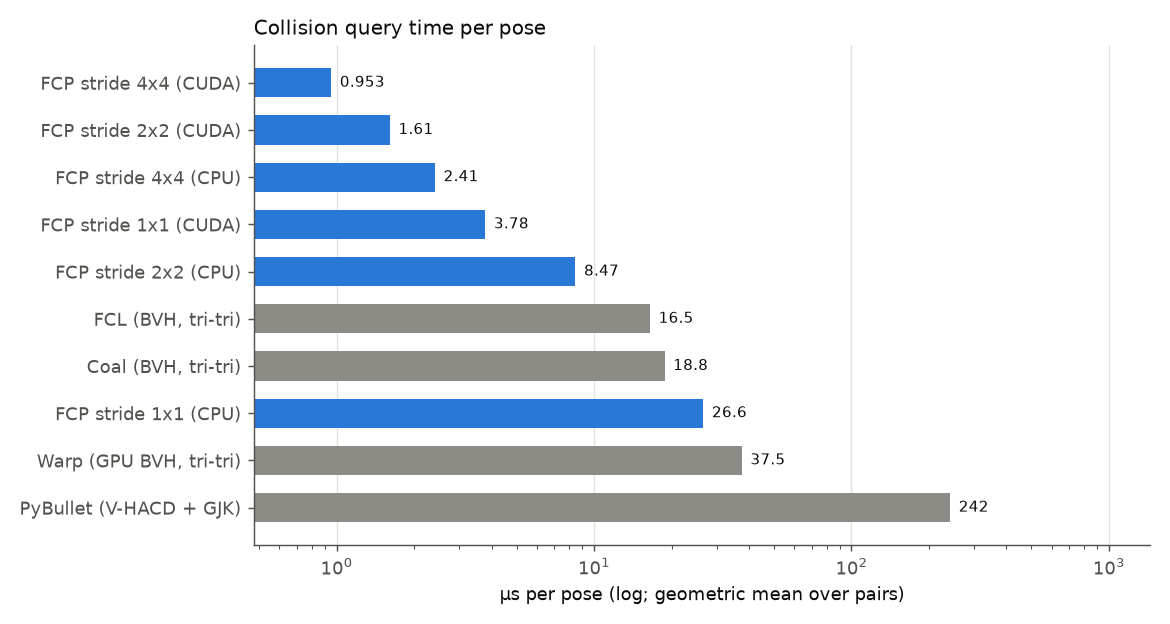
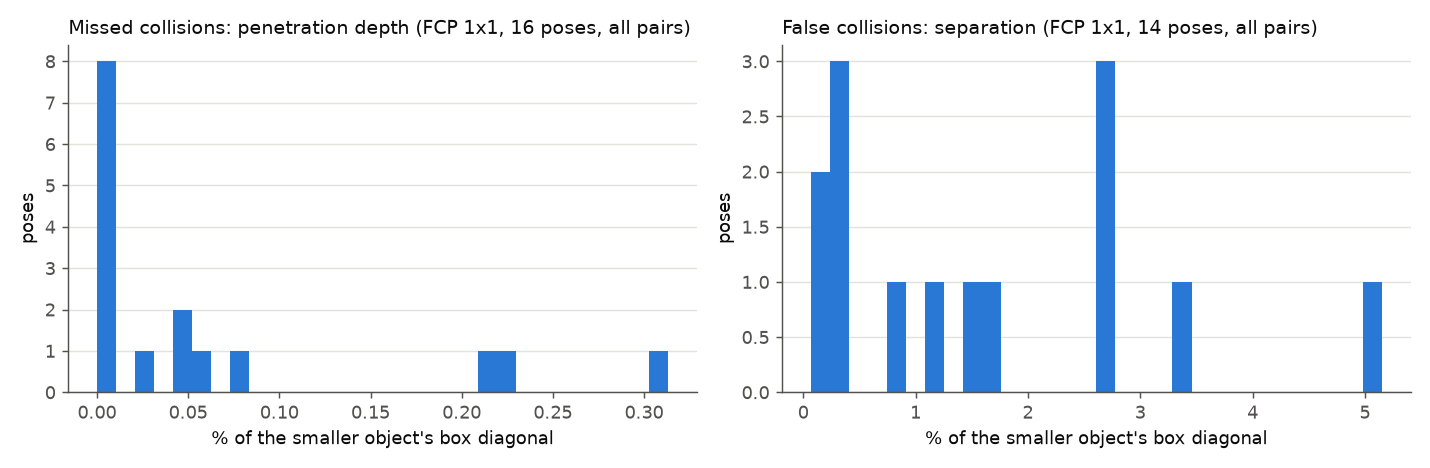
| method | device | mug-bowl µs/pose | dino-elephant µs/pose | shoe-horse µs/pose | mug-mug µs/pose | dress-horse µs/pose | geo-mean µs/pose | × vs Coal | build ms (mean) | accuracy vs mesh % | missed | false | accuracy vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FCP stride 4x4 (CUDA) | gpu | 1.48 | 0.867 | 0.75 | 1.27 | 0.647 | 0.953 | 19.7 | 28.3 | 99.49 | 45 | 6 | 99.65 |
| FCP stride 2x2 (CUDA) | gpu | 2.11 | 1.7 | 1.34 | 1.7 | 1.33 | 1.61 | 11.7 | 28.3 | 99.64 | 25 | 11 | 99.78 |
| FCP stride 4x4 (CPU) | cpu | 1.82 | 4.74 | 2.4 | 1.4 | 2.81 | 2.41 | 7.8 | 28.3 | 99.49 | 45 | 6 | 99.65 |
| FCP stride 1x1 (CUDA) | gpu | 4.25 | 3.56 | 3.7 | 3.53 | 3.9 | 3.78 | 5.0 | 28.3 | 99.70 | 16 | 14 | 99.80 |
| FCP stride 2x2 (CPU) | cpu | 5.96 | 14.2 | 12.1 | 4.67 | 9.12 | 8.47 | 2.2 | 28.3 | 99.64 | 25 | 11 | 99.78 |
| FCL (BVH, tri-tri) | cpu | 21.8 | 16 | 13.8 | 20.2 | 12.6 | 16.5 | 1.1 | 379.8 | 100.00 | 0 | 0 | 99.80 |
| Coal (BVH, tri-tri) | cpu | 24.7 | 17.5 | 15.2 | 23.6 | 15.1 | 18.8 | 1.0 | 279.1 | 100.00 | 0 | 0 | 99.80 |
| FCP stride 1x1 (CPU) | cpu | 21.1 | 50.1 | 23.7 | 16.8 | 31.6 | 26.6 | 0.7 | 28.3 | 99.70 | 16 | 14 | 99.80 |
| Warp (GPU BVH, tri-tri) | gpu | 22.8 | 24.9 | 28.4 | 20.3 | 226 | 37.5 | 0.5 | 4.265 | 100.00 | 0 | 0 | 99.80 |
| PyBullet (V-HACD + GJK) | cpu | 337 | 234 | 185 | 361 | 157 | 242 | 0.1 | 0.02959 | 98.67 | 0 | 133 | 98.49 |
mug-bowl: 8454 / 14030 faces, 66 % of 2000 poses collide; dino-elephant: 19690 / 52216 faces, 40 % of 2000 poses collide; shoe-horse: 24314 / 13840 faces, 39 % of 2000 poses collide; mug-mug: 8454 / 8454 faces, 62 % of 2000 poses collide; dress-horse: 444020 / 13840 faces, 31 % of 2000 poses collide


| method | device | pan_holes ns/pt | dog ns/pt | knot ns/pt | spring ns/pt | sponge ns/pt | gear ns/pt | geo-mean ns/pt | × vs Open3D | build ms (mean) | wrong vs mesh % | wrong vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
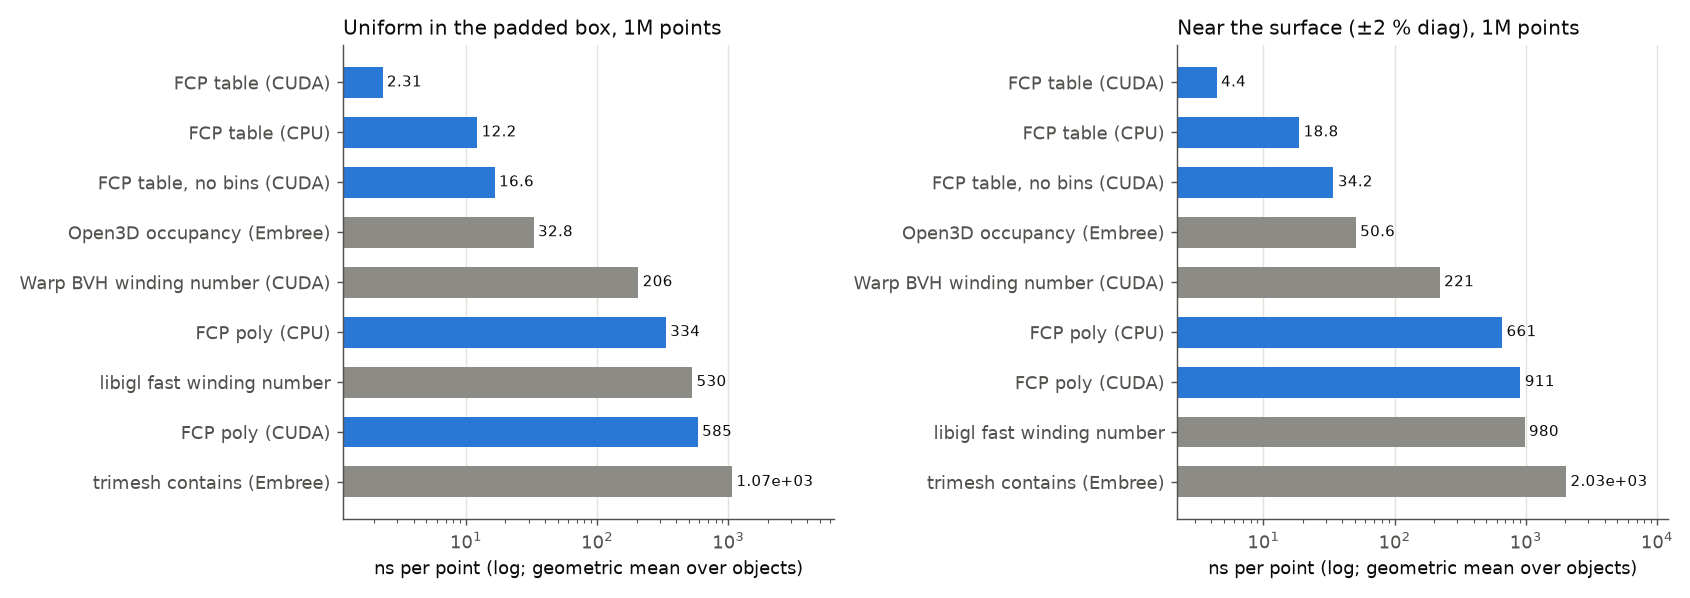
| FCP table (CUDA) | gpu | 5.88 | 4.69 | 3.17 | 6.73 | 7.33 | 1.69 | 4.4 | 11.5 | 6.35 | 8.04 | |
| FCP table (CPU) | cpu | 20.3 | 21.1 | 15 | 20.5 | 36.9 | 8.92 | 18.8 | 2.7 | 6.35 | 8.04 | |
| FCP table, no bins (CUDA) | gpu | 41.5 | 32.8 | 28.9 | 30.9 | 48 | 27.4 | 34.2 | 1.5 | 6.35 | 8.04 | |
| Open3D occupancy (Embree) | cpu | 49.6 | 73 | 50.2 | 58.1 | 50.2 | 31.6 | 50.6 | 1.0 | 0.32 | 0.00 | |
| Warp BVH winding number (CUDA) | gpu | 168 | 580 | 299 | 686 | 139 | 42.4 | 221 | 0.2 | 3.04 | 0.00 | |
| FCP poly (CPU) | cpu | 1.02e+03 | 567 | 733 | 584 | 725 | 465 | 661 | 0.1 | 6.35 | 7.52 | |
| FCP poly (CUDA) | gpu | 674 | 1.46e+03 | 1.34e+03 | 615 | 2.65e+03 | 266 | 911 | 0.1 | 6.35 | 7.52 | |
| libigl fast winding number | cpu | 1.57e+03 | 787 | 458 | 584 | 1.47e+03 | 1.81e+03 | 980 | 0.1 | 13 | 0.00 |
| method | device | pan_holes ns/pt | dog ns/pt | knot ns/pt | spring ns/pt | sponge ns/pt | gear ns/pt | geo-mean ns/pt | × vs Open3D | build ms (mean) | wrong vs mesh % | wrong vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FCP table (CUDA) | gpu | 2.66 | 1.97 | 1.08 | 3.88 | 5.55 | 1.26 | 2.31 | 14.2 | 6.35 | 1.44 | |
| FCP table (CPU) | cpu | 10.5 | 11.5 | 6.61 | 12.1 | 29.5 | 11.5 | 12.2 | 2.7 | 6.35 | 1.44 | |
| FCP table, no bins (CUDA) | gpu | 30.2 | 11.4 | 5.06 | 18.2 | 30.5 | 21.3 | 16.6 | 2.0 | 6.35 | 1.44 | |
| Open3D occupancy (Embree) | cpu | 31.4 | 35.2 | 25.5 | 38.4 | 46.1 | 24.9 | 32.8 | 1.0 | 0.32 | 0.00 | |
| Warp BVH winding number (CUDA) | gpu | 146 | 532 | 382 | 599 | 109 | 39.9 | 206 | 0.2 | 3.04 | 0.00 | |
| FCP poly (CPU) | cpu | 492 | 188 | 265 | 342 | 476 | 348 | 334 | 0.1 | 6.35 | 1.29 | |
| libigl fast winding number | cpu | 1.11e+03 | 240 | 159 | 249 | 1.38e+03 | 1.53e+03 | 530 | 0.1 | 13 | 0.00 | |
| FCP poly (CUDA) | gpu | 494 | 640 | 699 | 543 | 1.63e+03 | 205 | 585 | 0.1 | 6.35 | 1.29 |
| method | device | pan_holes ns/pt | dog ns/pt | knot ns/pt | spring ns/pt | sponge ns/pt | gear ns/pt | geo-mean ns/pt | × vs Open3D | build ms (mean) | wrong vs mesh % | wrong vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FCP table (CUDA) | gpu | 10.3 | 8.73 | 7.05 | 10.6 | 11.9 | 4.69 | 8.5 | 9.5 | 6.35 | 8.11 | 2.10 |
| FCP table (CPU) | cpu | 22.6 | 22.4 | 16.4 | 21.2 | 36.7 | 9.34 | 19.8 | 4.1 | 6.35 | 8.11 | 2.10 |
| FCP table, no bins (CUDA) | gpu | 48.3 | 40.8 | 35.4 | 36.3 | 59.9 | 32.9 | 41.3 | 1.9 | 6.35 | 8.11 | 2.10 |
| Open3D occupancy (Embree) | cpu | 81.6 | 111 | 79.1 | 87.3 | 82.1 | 53 | 80.5 | 1.0 | 0.32 | 0.00 | 7.33 |
| Warp BVH winding number (CUDA) | gpu | 192 | 526 | 275 | 651 | 182 | 44.1 | 229 | 0.4 | 3.04 | 0.00 | 7.33 |
| FCP poly (CPU) | cpu | 1e+03 | 571 | 755 | 581 | 762 | 469 | 669 | 0.1 | 6.35 | 7.57 | 2.01 |
| FCP poly (CUDA) | gpu | 959 | 1.64e+03 | 1.55e+03 | 908 | 2.82e+03 | 404 | 1.17e+03 | 0.1 | 6.35 | 7.57 | 2.01 |
| trimesh contains (Embree) | cpu | 2.2e+03 | 2.91e+03 | 1.63e+03 | 2.68e+03 | 2.28e+03 | 1.1e+03 | 2.03e+03 | 0.0 | 27.7 | 0.00 | 7.33 |
| libigl fast winding number | cpu | 2.59e+03 | 3.24e+03 | 1.91e+03 | 3.43e+03 | 1.59e+03 | 1.89e+03 | 2.34e+03 | 0.0 | 13 | 0.00 | 7.33 |

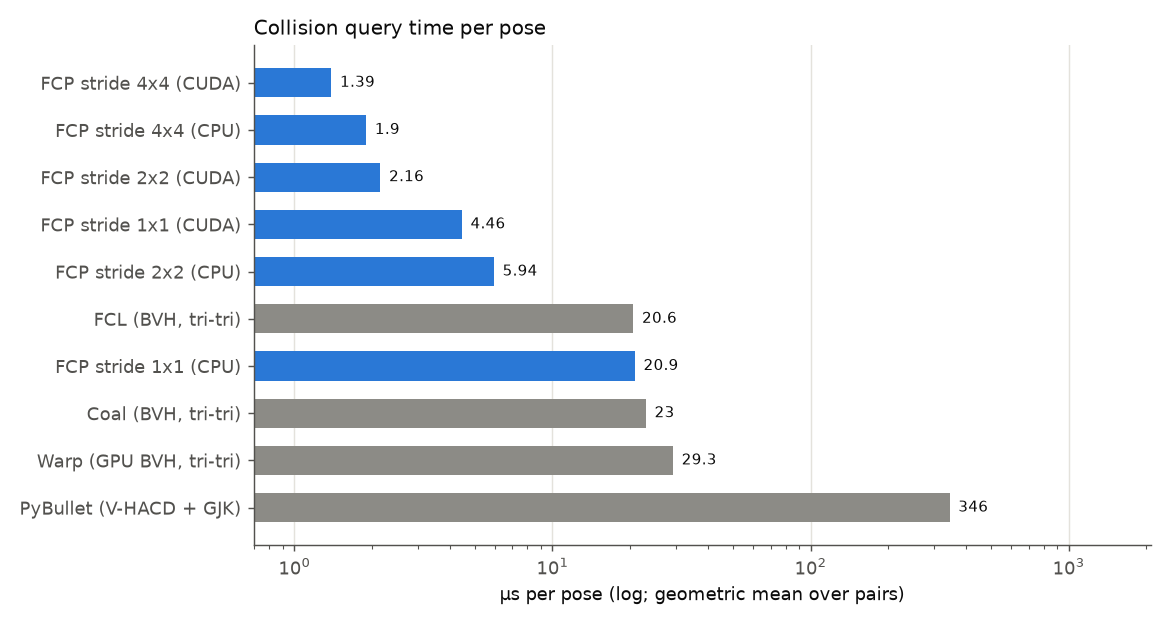
| method | device | spring-spring µs/pose | knot-knot µs/pose | sponge-sponge µs/pose | gear-gear µs/pose | pan_holes-dog µs/pose | knot-spring µs/pose | geo-mean µs/pose | × vs Coal | build ms (mean) | accuracy vs mesh % | missed | false | accuracy vs decoded % |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FCP stride 4x4 (CUDA) | gpu | 1.96 | 1.08 | 2.78 | 0.566 | 1.16 | 1.88 | 1.39 | 16.6 | 28.67 | 98.72 | 154 | 0 | 99.63 |
| FCP stride 4x4 (CPU) | cpu | 0.645 | 3.97 | 7.35 | 0.803 | 1.53 | 2.03 | 1.9 | 12.1 | 28.67 | 98.72 | 154 | 0 | 99.63 |
| FCP stride 2x2 (CUDA) | gpu | 2.52 | 2.03 | 4.81 | 0.865 | 1.67 | 2.82 | 2.16 | 10.7 | 28.67 | 98.97 | 123 | 1 | 99.82 |
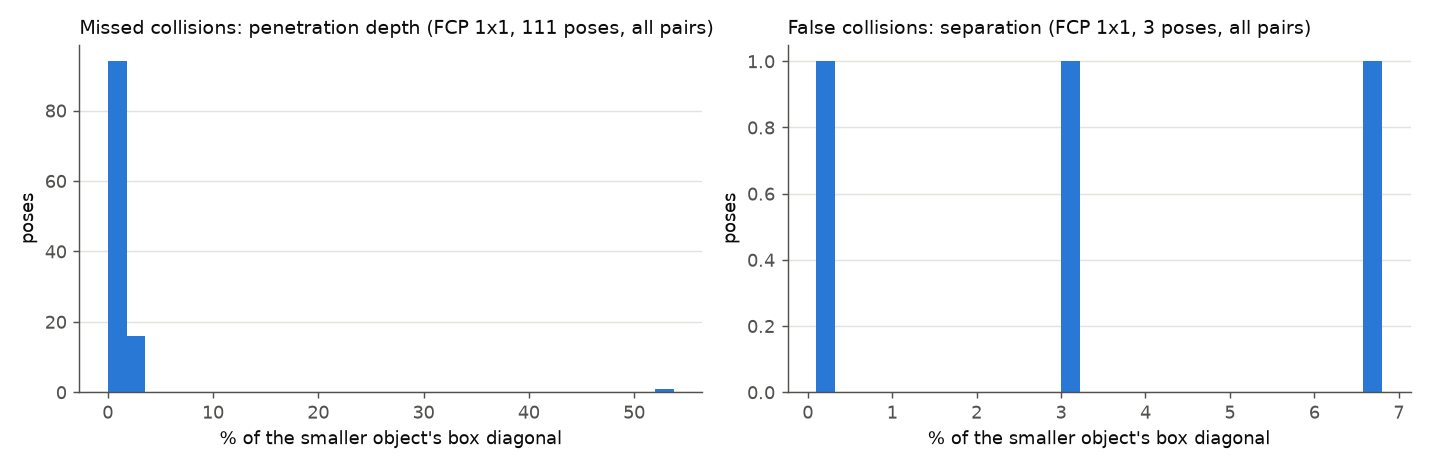
| FCP stride 1x1 (CUDA) | gpu | 3.02 | 6.98 | 14.3 | 1.75 | 2.96 | 5.04 | 4.46 | 5.2 | 28.67 | 99.05 | 111 | 3 | 99.90 |
| FCP stride 2x2 (CPU) | cpu | 1.76 | 13.8 | 22.4 | 2.77 | 4.25 | 6.85 | 5.94 | 3.9 | 28.67 | 98.97 | 123 | 1 | 99.82 |
| FCL (BVH, tri-tri) | cpu | 24.6 | 15.3 | 32.8 | 14.6 | 23.9 | 17.8 | 20.6 | 1.1 | 206.1 | 100.00 | 0 | 0 | 99.05 |
| FCP stride 1x1 (CPU) | cpu | 5.92 | 51.4 | 74.3 | 10.3 | 14.2 | 25.1 | 20.9 | 1.1 | 28.67 | 99.05 | 111 | 3 | 99.90 |
| Coal (BVH, tri-tri) | cpu | 26.1 | 16.1 | 40.1 | 15.4 | 29.3 | 19.5 | 23 | 1.0 | 150.8 | 100.00 | 0 | 0 | 99.05 |
| Warp (GPU BVH, tri-tri) | gpu | 51.7 | 28.1 | 13.8 | 11.3 | 82 | 34.2 | 29.3 | 0.8 | 7.797 | 100.00 | 0 | 0 | 99.05 |
| PyBullet (V-HACD + GJK) | cpu | 485 | 180 | 701 | 287 | 356 | 274 | 346 | 0.1 | 1.356e+04 | 98.77 | 0 | 147 | 97.84 |
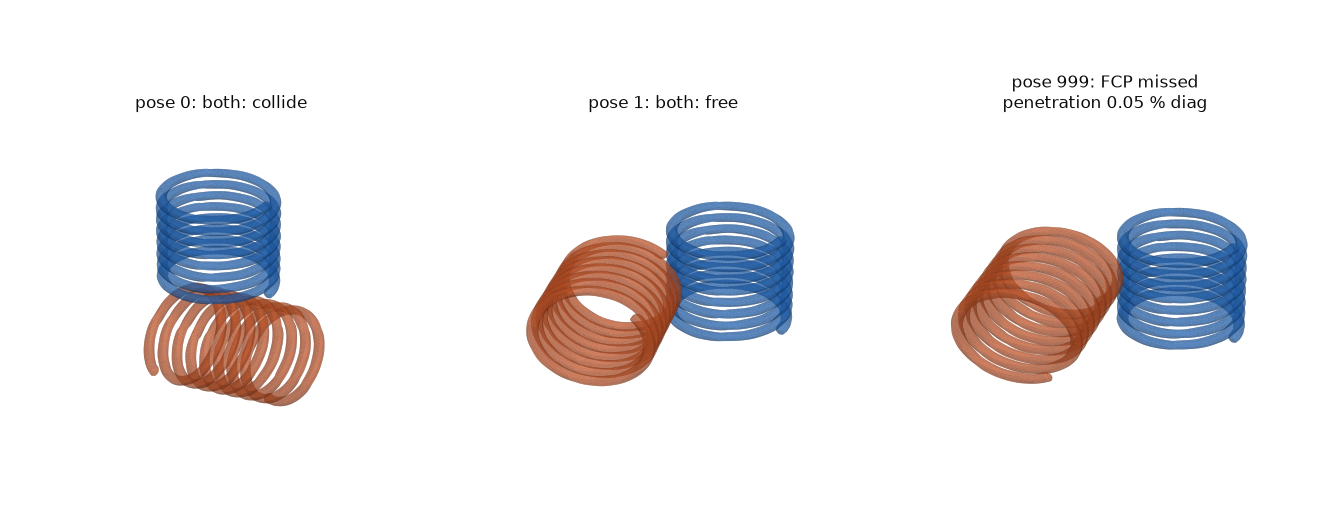
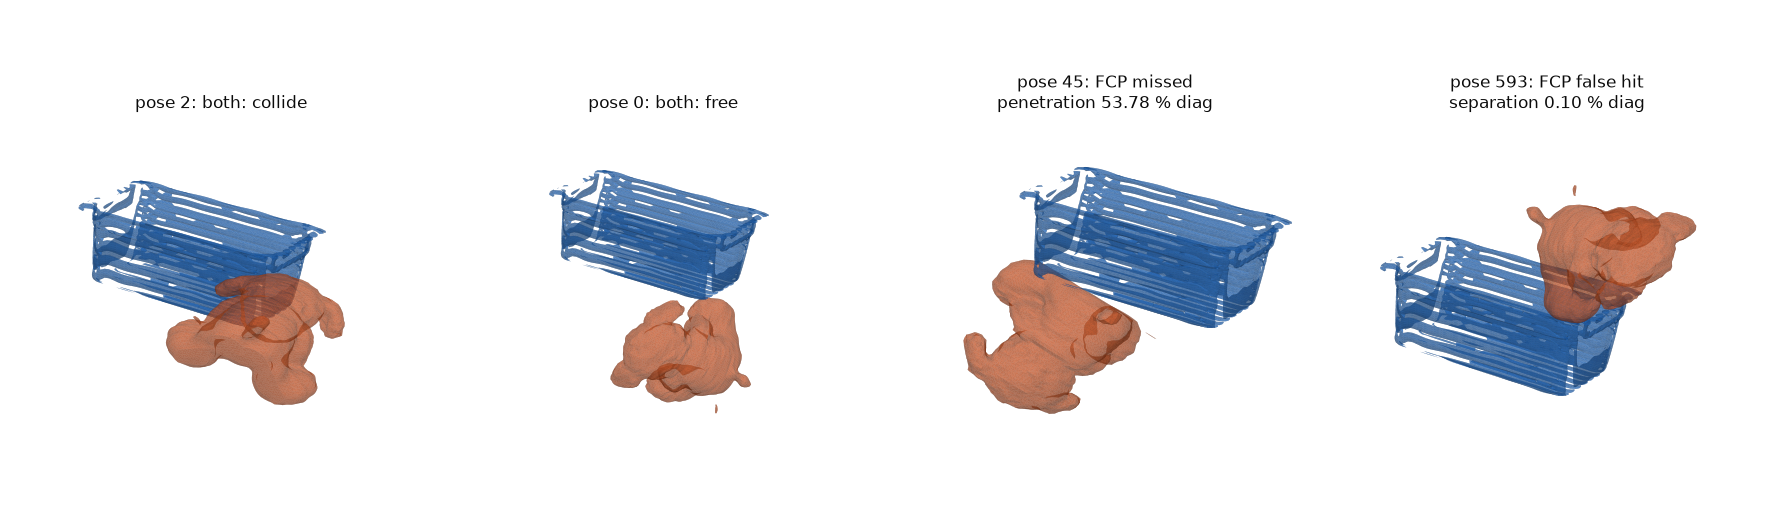
spring-spring: 76796 / 76796 faces, 77 % of 2000 poses collide; knot-knot: 28800 / 28800 faces, 52 % of 2000 poses collide; sponge-sponge: 1300 / 1300 faces, 75 % of 2000 poses collide; gear-gear: 992 / 992 faces, 76 % of 2000 poses collide; pan_holes-dog: 16092 / 67204 faces, 57 % of 2000 poses collide; knot-spring: 28800 / 76796 faces, 59 % of 2000 poses collide



Scripts in ../scripts (fcpq.py = the descriptor queries, points_bench.py, collide_bench.py (FCP_SET=complex for section 2), make_shapes.py, renders.py, report.py); raw numbers in points*.csv, collide*.csv, logs alongside. The first run at 2048 atoms: a2048/.